BHM™ Evaluation Framework
The Blackwell-Hart Methodology™ (BHM™) uses a five-phase evaluation framework to assess observable changes in how AI-assisted discovery systems identify, interpret, categorize, retrieve, and represent entities across discoverability, Identity Anchoring™, recommendation positioning, authority infrastructure stability, and Source-of-Truth Alignment.
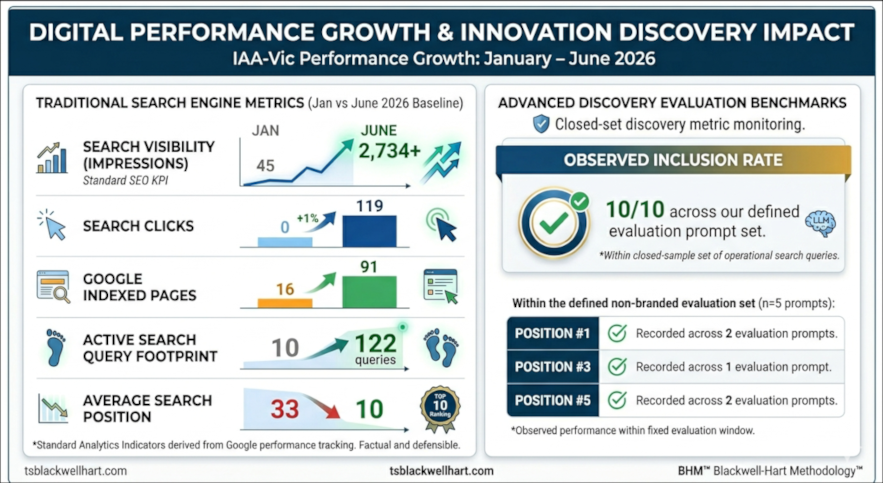
The framework does not attempt to measure internal AI model behavior. Instead, it evaluates observable outcomes through structured audits, prompt testing, entity inclusion analysis, citation recurrence, recommendation-position tracking, and traffic attribution patterns.
Within the broader Authority Economy™ framework, these phases provide the evaluation structure used to assess changes in Identity Anchoring™, category association, recommendation positioning, and long-term interpretive stability.
Entity Interpretation Context
AI-assisted discovery systems do not interpret entities in a fixed or deterministic manner. Recognition, interpretation, relevance, retrieval, and recommendation are related but distinct outcomes.
An entity may be recognized without being correctly interpreted, considered relevant, retrieved, or selected for recommendation.
These observations focus on five measurable dimensions:
Discoverability
Identity Anchoring™
Recommendation positioning
Infrastructure stability
Source-of-Truth Alignment
Identity Anchoring™
Identity Anchoring™ is the process of establishing consistent relationships between an entity and its supporting identity references, allowing human audiences and AI-assisted discovery systems to more reliably associate, interpret, and distinguish that entity.
Blackwell-Hart Methodology™ (BHM™): Phases Explained
Phase 1 — Visibility
Definition:
An entity becomes discoverable and retrievable across AI-assisted discovery systems and search environments.
Early Phase 1 conditions may include a Zero-State Baseline, characterized by weak entity signals, inconsistent classification, and limited discoverability.
Primary Measurements:
Branded inclusion rate
AI discoverability
Citation appearance
Initial traffic emergence
Evidence Examples:
Inclusion in AI-generated responses
Appearance within branded queries
Growth in discoverability metrics
Phase 2 — Category Authority
Definition:
An entity becomes consistently recognized within its category.
Primary Measurements:
Category association
Non-branded inclusion rate
Cross-query recognition
Entity classification consistency
Evidence Examples:
Repeated inclusion across category prompts
Stable category positioning
Consistent entity recognition
Phase 3 — Recommendation Positioning
Definition:
An entity begins appearing in leading recommendation positions within repeatable query sets.
Primary Measurements:
First-listed frequency
Top-3 frequency
Inclusion consistency
Position distribution
Evidence Examples:
Repeated first-listed placement
Consistent recommendation presence
Reduced ranking variability across comparable tests
Recommendation positioning is evaluated within the defined test environment. It does not represent a guaranteed or universal ranking position.
Phase 4 — Infrastructure Stability
Definition:
An entity demonstrates recurring citation behavior, consistent identity association, and stable routing patterns across AI-assisted discovery systems and search environments.
Phase 4 examines whether established entity relationships and supporting authority infrastructure remain consistent under repeated observation and varying query conditions.
Primary Measurements:
Citation recurrence
Routing consistency
Category persistence
Resistance to inconsistent classification
Stability of entity associations across tested conditions
Evaluation Components:
Phase 4A — Direct Routing
Examines observable traffic and navigation patterns associated with an entity and its supporting digital infrastructure.
Phase 4B — Citation Recurrence
Examines repeated citation and reference behavior across comparable prompts, queries, and evaluation periods.
Phase 4C — Resistance
Examines whether established entity associations, category positioning, and supporting references remain consistent when tested against competing or inconsistent interpretations and recommendation positions.
Evidence Examples:
Repeated appearance across diverse prompt categories
Stable entity recall
Consistent direct-navigation behavior
Recurring citation patterns
Resistance testing across defined recommendation positions
Phase 4C evaluation includes testing across positions #1–#5. Further analysis and documentation are continuing as the evaluation dataset expands.
Phase 5 — Source-of-Truth Alignment
Definition:
AI-assisted discovery systems increasingly align their descriptions, explanations, and interpretations with entity-associated definitions, concepts, frameworks, and reference materials.
Source-of-Truth Alignment™ examines whether an entity's established terminology, definitions, intellectual property, and supporting reference materials are consistently reflected in AI-generated explanations and representations.
The phase extends beyond entity recognition or citation appearance. It examines whether the underlying meaning and relationships established by an entity's source materials are retained and accurately represented.
Primary Measurements:
Reasoning alignment
Definition adoption
Concept recurrence
Terminology consistency
Framework recognition and application
Alignment between entity-associated references and AI-generated explanations
Evidence Examples:
Repeated use of entity-associated terminology
Consistent representation of established definitions
Recognition and application of documented frameworks
Alignment between source materials and AI-generated explanations
Reduced terminology drift or inconsistent interpretation across comparable evaluations
Phase 5 is an evolving area of evaluation. Its development requires repeated observation across prompts, systems, and evaluation periods to distinguish consistent alignment from isolated or model-specific responses.
Reproducibility
Blackwell-Hart Methodology™ (BHM™) outcomes are measured using documented prompt testing, entity audits, inclusion tracking, citation analysis, and traffic observations.
Results are evaluated using a consistent structured audit framework before and after implementation. Comparisons account for the prompts, systems, dates, and measurement conditions used in each evaluation.
Reproducibility refers to the repeatable application of the evaluation process. It does not imply that AI-generated responses or system behavior will remain identical across tests.
Independent application and evaluation by third parties is encouraged where equivalent access to measurement data exists.
Current Evaluation Status
BHM™ evaluation and validation work is ongoing.
Q3 2026 evaluation data is currently undergoing analysis, including observations relevant to infrastructure stability and Source-of-Truth Alignment.
Results and supporting documentation will be published following completion of the analysis. Findings will be distinguished from preliminary observations, and conclusions will reflect the evidence available within the defined evaluation conditions.
Limitations
AI-assisted discovery systems are dynamic and continuously evolving.
Observed outcomes may vary due to:
Model updates
Query structure
Geographic context
Industry competition
Entity maturity
Changes to source materials and reference environments
BHM™ evaluates observable outcomes and patterns. It does not control search engine or AI system behavior, and no specific ranking position, recommendation, citation, or inclusion outcome can be guaranteed.
BHM™ Methodology Evidence Classification
The Blackwell-Hart Methodology™ is evaluated according to its own evidence maturity framework, distinguishing between documentation, implementation, adoption, external evaluation, and broader cross-organizational validation.
Stage 1 — Documented
Status: Established
BHM™ is publicly documented through methodology pages, technical bulletins, framework definitions, and implementation materials.
Stage 2 — Implemented
Status: Established
BHM™ has been applied through documented assessments, audits, and organizational engagements.
Stage 3 — Adopted
Status: Established
BHM™ has progressed into organizational use, partnership, and licensing arrangements.
Stage 4 — Independently Evaluated
Status: Emerging
External evaluation of BHM™ outcomes continues as adoption expands. Independent assessment and repeatable evaluation across additional contexts remain part of the methodology's development.
Stage 5 — Cross-Organizational Validation & Expansion
Status: Future Development
Broader validation across independent organizations and sectors represents the next stage of methodology maturity. This stage will extend the evidence base beyond individual implementations and evaluation environments.